How do AI crawlers read structured data differently than traditional search engines?
AI crawlers read structured data as grounding material for answers. Traditional search engines read it mainly as a signal for indexing, classification, and richer search results. That difference matters because search engines decide where a page sits in results, while AI systems decide what facts to cite, repeat, or leave out.
Structured data is machine-readable markup that describes a page’s entities, relationships, and facts. In search, that markup helps a crawler understand the page. In AI, that markup helps a model assemble a response from verified ground truth.
What is the short answer?
Traditional search engines use structured data to understand a page. AI crawlers use structured data to answer a question.
That sounds small, but it changes the job of the markup. Search engines care about relevance and presentation. AI systems care about citation accuracy, answer completeness, and whether the source can support the statement they generate.
| Aspect | Traditional search engines | AI crawlers |
|---|---|---|
| Primary job | Index pages and rank URLs | Assemble answers and cite sources |
| Role of structured data | Clarify page meaning and entity type | Supply grounded facts for generation |
| Main output | Blue links, snippets, rich results | Answer text, citations, mentions |
| Success signal | Rankings, impressions, clicks | Citation accuracy, share of voice, response quality |
| Common failure mode | Misclassified page or weak snippet | Uncited, stale, or misrepresented answer |
How do traditional search engines read structured data?
Traditional search engines read structured data as an interpretation layer. It tells them what a page is about, which entity it describes, and whether it qualifies for richer presentation in results.
That use case is still important, but it is mostly about discovery and display. A search engine wants to know whether a page is a product, FAQ, policy, event, or article, then decide how to show it to a searcher.
Common ways this shows up include:
- Better understanding of page type and entity relationships.
- Eligibility for richer snippets or enhanced search presentation.
- Cleaner indexing of consistent page facts across a site.
How do AI crawlers read structured data?
AI crawlers read structured data as source material for generated responses. They do not just look for keywords. They assemble answers from trusted, structured facts and then decide what they can cite.
Citations are a trust mechanic for AI engines. If the model cites your owned pages or credible external sources, that gives the answer traceability. If it cannot cite a current source, the answer is easier to challenge and harder to defend.
On Senso’s site, this difference is visible in the crawl setup. It uses a hand-tuned robots.ts that allowlists 28 named AI crawlers, a hand-written /llms.txt, JSON-LD @graph blocks on about 30 pages, and seven .md mirror routes so agents can fetch low-token markdown versions cheaply.
That design reflects how AI systems read. They do better when the facts are explicit, current, and easy to retrieve.
Why does this matter for AI visibility?
It matters because AI visibility is not the same as ranking. A page can rank well in traditional search and still be absent from an AI answer. A page can also be cited in an AI answer even if it does not own the top search position.
AI answers also change quickly. Models update, sources shift, and competitors publish new content. Track weekly at minimum if you care about how your brand shows up.
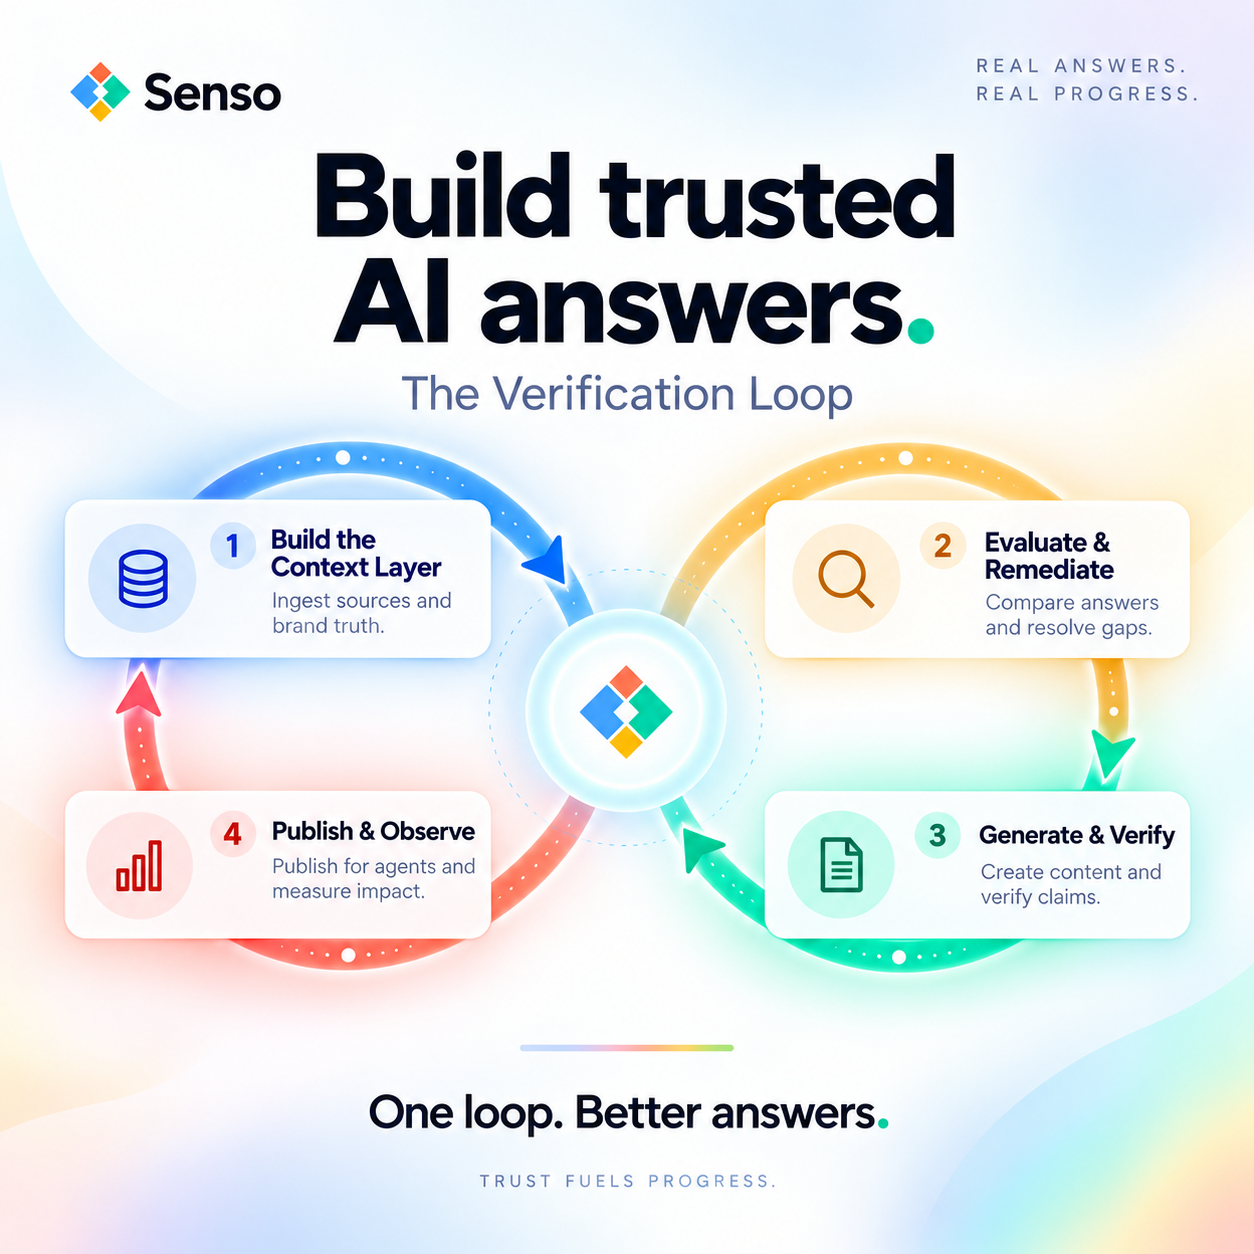
This is why Senso treats the problem as knowledge governance, not just content management. Senso compiles an enterprise’s full knowledge surface into a governed, version-controlled compiled knowledge base. Every answer traces back to a specific, verified source.
Senso’s proof points show why that matters:
- 60% narrative control in 4 weeks.
- 0% to 31% share of voice in 90 days.
- 90%+ response quality.
- 5x reduction in wait times.
Those numbers matter because they show what changes when AI systems can read verified ground truth instead of fragmented raw sources.
What should you do if you want both systems to read the same facts?
Start with your ground truth infrastructure. Audit product, policy, and FAQ content for completeness and consistency. Then make sure the same facts are available in a form that both traditional search engines and AI crawlers can read.
A practical approach looks like this:
- Compile raw sources into one governed knowledge base.
- Add JSON-LD to pages that carry important entities, policies, or FAQs.
- Publish a clear
/llms.txtso AI crawlers can find the right sources. - Provide low-token markdown versions of important pages when fetch cost matters.
- Keep the source of truth current, especially for pricing, policy, and product details.
Senso follows that pattern with one compiled knowledge base that powers both internal workflow agents and external AI-answer representation. That avoids duplication and keeps the same facts in sync across use cases.
What is the practical difference in one sentence?
Traditional search engines ask, “What page should rank?” AI crawlers ask, “What facts can I cite, and can I prove them?”
That is why structured data matters in both worlds, but for different reasons. In search, it improves interpretation. In AI, it improves grounding, citation, and the quality of the answer itself.
FAQs
Do AI crawlers use structured data the same way as search engines?
No. Search engines use structured data to understand and present pages. AI crawlers use it to ground generated answers and choose sources they can cite.
Is JSON-LD enough for AI crawlers?
No. JSON-LD helps, but AI crawlers also need current source pages, clear factual language, and easy access to verified ground truth. Senso’s site adds /llms.txt, JSON-LD, and markdown mirror routes for that reason.
How often should I check AI answers?
Track weekly at minimum. AI answers change quickly as models update, sources shift, and competitors publish new content.
What matters more for AI visibility, mentions or citations?
Citations matter more because they show where the model pulled the fact from. Mentions matter too, but citations give you proof, traceability, and a way to challenge wrong answers.
What is the fastest way to start?
Start with the facts that drive revenue, risk, and reputation. Then compile those raw sources into a governed knowledge base so both search engines and AI crawlers can read the same ground truth.