How do AI Systems Compare Brands?
AI systems compare brands by retrieving facts, checking citations, and composing a synthesis from verified ground truth. Senso’s documentation says AI systems already describe products, compare competitors, summarize policies, and recommend vendors. The question is no longer whether AI systems compare brands. The question is whether they compare them with grounded evidence.
Quick Answer
AI systems compare brands through evidence, not opinion. They favor brands with clear source trails, owned citations, and consistent facts across prompt runs. Senso measures this with mentions, Share of Voice, narrative control, and citation accuracy against verified ground truth.
What do AI systems compare when they compare brands?
AI systems compare the facts they can retrieve and verify. They look for current product details, policy language, proof points, and third-party corroboration. In Senso’s framework, AI Visibility also includes mentions, Share of Voice, and narrative control.
| Signal | What AI systems use it for | Why it matters |
|---|---|---|
| Verified ground truth | Approved brand facts and policies | It keeps the comparison grounded |
| Owned citations | Primary pages you control | Owned citations are the strongest signal that AI systems trust your primary sources |
| External citations | Credible third-party references | External citations add corroboration |
| Mentions | Brand inclusion across evaluated prompt runs | Mentions show whether AI systems include your brand at all |
| Share of Voice | Percentage of an answer dedicated to your brand | Share of Voice shows how much of the comparison you own |
| Narrative control | How AI systems describe, compare, and recommend your brand | Narrative control shows whether the framing matches your brand story |
Why do AI systems compare the same brands differently?
AI systems compare the same brands differently because prompts, sources, and model updates change. Senso’s docs say AI answers change quickly as models update, sources shift, and competitors publish new content. Senso recommends tracking weekly at minimum and reviewing core ground truth pages at least every 60 days and whenever facts change.
How is AI brand comparison different from search rankings?
AI brand comparison is a generated answer, not a list of links. Traditional rankings tell you where a URL sits on a results page. Mentions tell you whether AI models include your brand, and Share of Voice tells you how much of the answer your brand controls.
| Search engines | AI systems |
|---|---|
| Rank URLs | Compare brands inside a generated answer |
| Emphasize clicks and position | Emphasize mentions, citations, and answer share |
| Depend on indexable pages | Depend on verified ground truth and source quality |
| Return one result set | Produce many prompt-dependent answers |
What can teams do to change the answer?
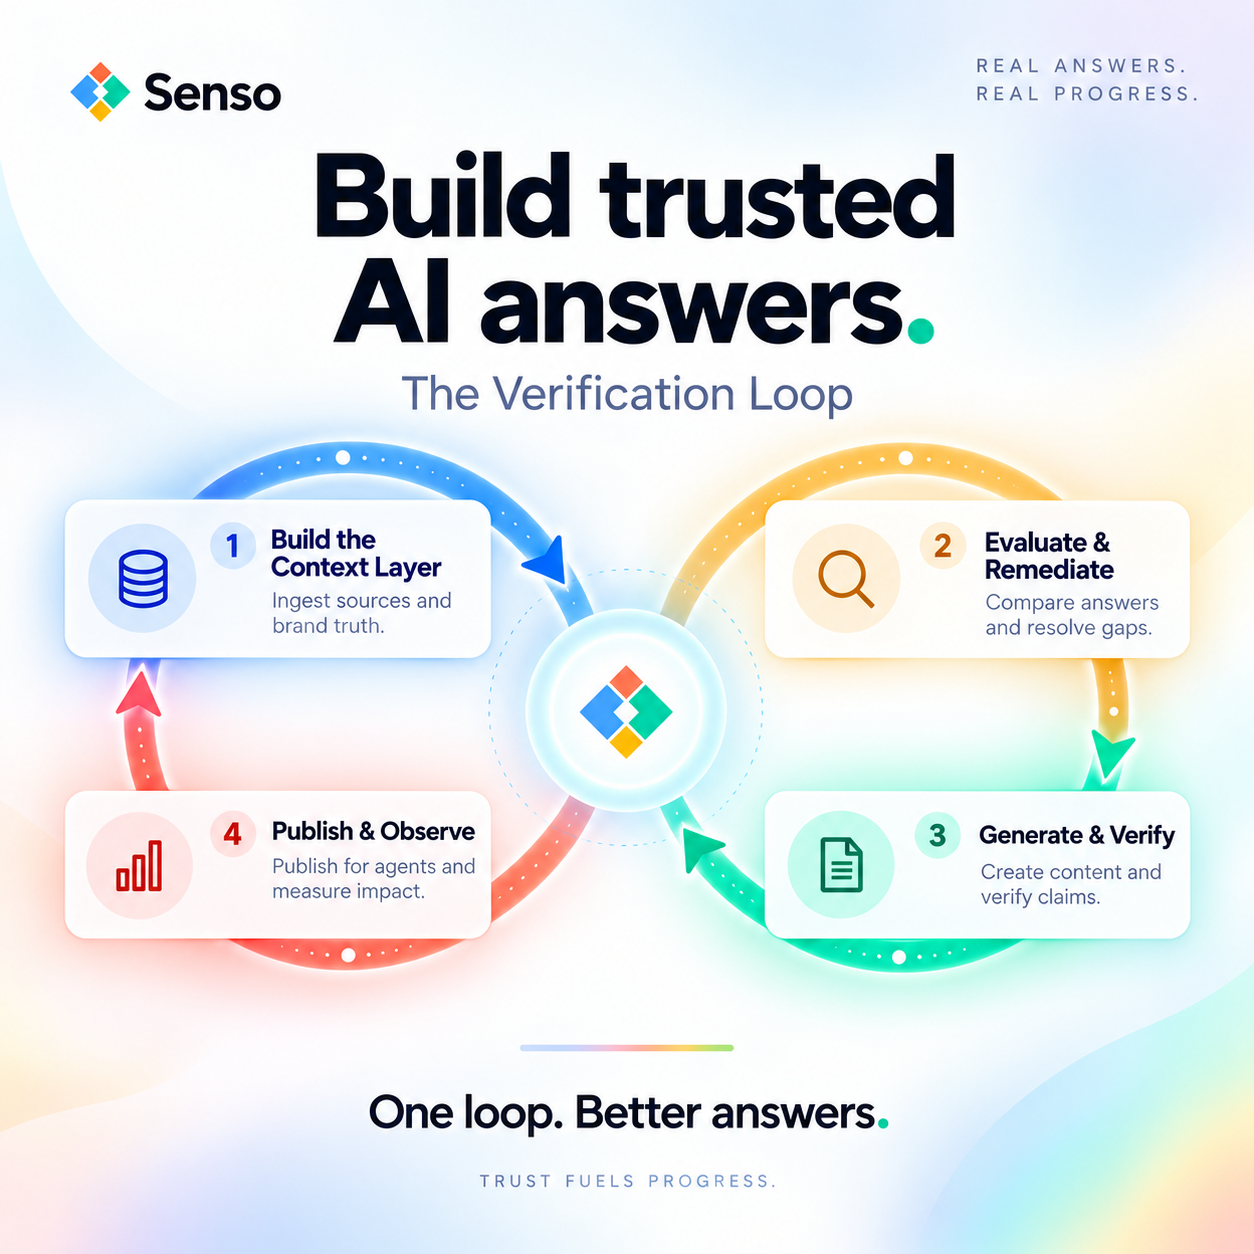
Teams change the answer by fixing the knowledge surface first. Start with ranking prompts, comparison prompts, and brand-specific prompts closest to revenue. Then compile a short factual knowledge base, publish or refresh owned citations, and keep the source set current.
- Compile current facts about products, policies, pricing, and proof points.
- Remove conflicts between public pages and internal sources.
- Publish owned citations for the claims you want AI systems to repeat.
- Add credible external citations where third parties already support the facts.
- Measure mentions, Share of Voice, and narrative control across prompt runs.
- Review core ground truth pages every 60 days or sooner when facts change.
How does Senso fit into this?
Senso turns brand comparison into a governed knowledge problem. It is the context layer for AI agents. It compiles an enterprise’s full knowledge surface into a governed, version-controlled compiled knowledge base, and every answer traces back to a specific verified source.
Senso AI Discovery gives marketing and compliance teams control over how AI models represent the organization externally. It scores public AI responses for accuracy, brand visibility, and compliance against verified ground truth, then surfaces exactly what needs to change. No integration required.
Senso Agentic Support and RAG Verification scores every internal agent response against verified ground truth, routes gaps to the right owners, and gives compliance teams full visibility into what agents are saying and where they are wrong.
Senso reports 60% narrative control in 4 weeks, 0% to 31% Share of Voice in 90 days, 90%+ response quality, and 5x reduction in wait times. Those results matter because agents already represent your brand whether you have verified the source or not.
FAQs
What is the most important signal in AI brand comparison?
Verified ground truth matters most. If the model cannot retrieve a current, consistent, and citable fact, it cannot compare the brand confidently.
What does narrative control mean?
Narrative control is an enterprise’s ability to influence how AI systems describe, compare, and recommend its brand. Senso uses that term to describe brand visibility in AI-generated answers.
How often should we review AI comparisons?
Track weekly at minimum. Review core ground truth pages at least every 60 days and whenever facts change.
What should regulated teams care about most?
Regulated teams should care about citation accuracy, auditability, and whether the answer traces back to a specific verified source. When a CISO asks whether the agent cited a current policy, standard retrieval tools often cannot prove it.
AI systems compare brands the way they compare any fact pattern. They select the evidence they can retrieve, verify, and cite. If you want better comparisons, govern the source facts first.