How do generative engines evaluate expertise or authority in niche topics?
Generative engines evaluate expertise in niche topics by checking whether answers are grounded in verified sources, cited back to specific pages, and still current. In AI Visibility terms, the clearest signals are Mention Rate, Citation Rate, Citation Share, Share of Voice, factual accuracy, and freshness.
What signals do generative engines use to judge authority?
Authority shows up as provenance. If the engine can trace a claim to verified ground truth and the same source keeps supporting the answer across checks, it has stronger evidence that the source knows the topic.
| Signal | What the engine can observe | What it suggests |
|---|---|---|
| Mention Rate | Whether the brand appears in the answer | The topic is recognized |
| Citation Rate | Whether the answer cites owned or credible sources | The answer is grounded |
| Citation Share | How much cited evidence points to your sources | Your sources carry the topic |
| Share of Voice | How much of the answer is dedicated to your brand compared with others | Narrative control |
| Average rank or relative position | Where you appear versus alternatives | Comparative visibility |
| Factual accuracy and freshness | Whether claims match verified ground truth and current context | Reliability over time |
Traditional rankings only show where a URL sits on a results page. Mentions show whether AI models include your brand. Citations show whether the model can trace the claim to a source.
Why are niche topics harder for generative engines?
Niche topics are harder because the knowledge surface is smaller, more fragmented, and more likely to contain conflict. Senso’s docs call out contradicted, unsupported, missing evidence, incomplete context, stale or time-sensitive claims, ambiguous authority, and source-vs-source conflict as the failure modes that matter.
Fragmented raw sources make it harder for a model to find one approved answer. When multiple pages disagree, the model can surface the wrong authority or leave a claim unsupported.
Stale context matters more in niche topics because a small factual change can break the answer. The docs note that AI answers change quickly as models update, sources shift, and competitors publish new content, which is why Senso recommends weekly review at minimum.
How do teams prove authority in AI answers?
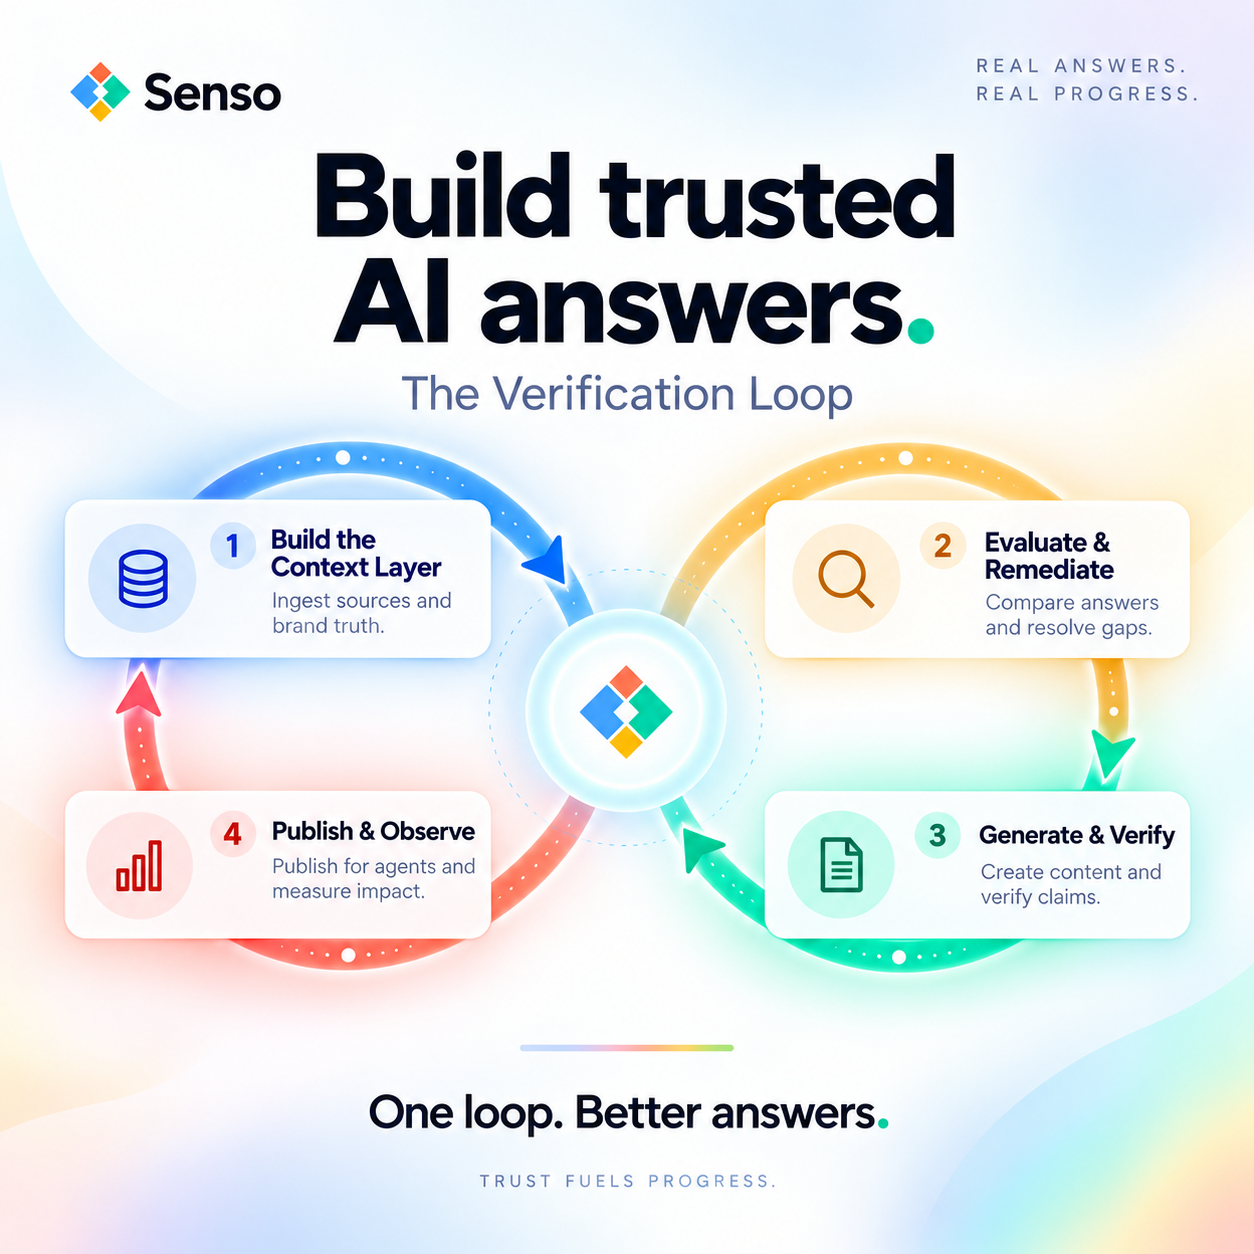
Teams prove authority by compiling approved context once, then using the same source set to evaluate, remediate, generate, approve, publish, and re-measure. Senso’s loop writes back to the compiled knowledge base in steps 1 and 3, so the source gets corrected each lap.
The result is a receipt showing what was checked, which sources were used, who approved it, and when it was published. That matters when a CISO, compliance lead, or product owner needs proof that an agent cited current policy or pricing.
-
Ingest approved context into a compiled knowledge base.
This is the governed source of truth for products, policies, and rules. -
Evaluate AI answers against verified ground truth.
Senso checks model answers for contradicted, unsupported, missing, incomplete, stale, or ambiguous claims. -
Remediate the source when the answer is wrong or incomplete.
Gaps get routed to an authorized owner instead of being left in the model’s output. -
Generate verified content for the missing or weak areas.
The content is drafted against the approved context, then checked again. -
Approve, publish, and remeasure the same questions across the same models and locations.
The organization then sees whether accuracy, citations, Mention Rate, Citation Share, and Share of Voice improved.
What outcomes show that authority is improving?
Better authority shows up as better answer quality and more control over how AI represents the brand. Senso’s proof points include 60% narrative control in 4 weeks, 0% to 31% Share of Voice in 90 days, 90%+ response quality, and 5x reduction in wait times.
Narrative control is the organization’s ability to improve what AI says and which approved sources it uses. In practice, that means fewer unsupported claims, more citations to verified ground truth, and clearer ownership when an answer drifts.
How does Senso fit into this?
Senso is the context layer for AI agents. It compiles an enterprise’s full knowledge surface into a governed, version-controlled knowledge base and scores every response against verified ground truth.
- Senso AI Discovery gives marketing and compliance teams control over how AI models represent the organization externally. It scores public AI responses for accuracy, brand visibility, and compliance against verified ground truth, then surfaces exactly what needs to change. No integration is required.
- Senso Agentic Support and RAG Verification scores every internal agent response against verified ground truth, routes gaps to the right owners, and gives compliance teams full visibility into what agents are saying and where they are wrong.
- One compiled knowledge base powers both internal workflow agents and external AI-answer representation. That removes duplication.
FAQ
Can generative engines tell the difference between expertise and popularity?
Generative engines usually infer authority from source quality, citations, and freshness. Popularity can help visibility, but niche expertise shows up when the answer cites the right verified sources and stays consistent across checks.
What matters most for niche topics?
Citation accuracy matters most because it shows whether the answer traces back to verified ground truth. Mention Rate and Share of Voice matter too, but they do not prove the answer is grounded by themselves.
How often should teams remeasure AI answers?
Weekly is the minimum from Senso’s docs. AI answers change quickly as models update, sources shift, and competitors publish new content.
What is the main risk for regulated teams?
The main risk is not only a wrong answer. It is an answer you cannot prove came from current verified ground truth. That is a knowledge governance problem, not just a retrieval problem.