How should I adapt my content strategy for LLMs?
LLMs already answer questions about your products, policies, and pricing. If your content is not grounded and current, the model will still answer, but it may represent you poorly. Adapt by moving from page volume to knowledge governance, with one compiled source of truth, answer-first pages, and a remediation loop tied to the questions that matter most.
Quick Answer
The best approach is to start with the prompts closest to revenue and risk. Build one governed knowledge base from verified ground truth, then rewrite the pages LLMs are most likely to use so the answer appears first. Senso has documented 60% narrative control in 4 weeks and 0% to 31% share of voice in 90 days when teams govern the knowledge surface.
- Audit product and policy content for completeness and consistency.
- Prioritize ranking prompts, comparison prompts, and brand-specific questions.
- Measure citation accuracy, response quality, and changes in AI visibility.
Top Priorities at a Glance
| Rank | Priority | Best for | Primary strength | Main tradeoff |
|---|---|---|---|---|
| 1 | Governed knowledge base | Regulated teams and agent-heavy orgs | One verified source for answers | Requires an upfront content audit |
| 2 | Answer-first pages | Existing editorial, FAQ, and support content | Easier for LLMs to extract grounded facts | Less room for long brand narrative |
| 3 | Revenue-linked prompt focus | Teams needing visible impact fast | Aligns work with high-value questions | Leaves lower-priority content for later |
| 4 | Discovery surface alignment | Sites with frequent publishing | Reduces drift across public surfaces | Needs a deliberate publishing process |
| 5 | Measurement and remediation loop | Compliance, support, and ops teams | Turns wrong answers into edits | Needs owners and a review cadence |
How We Ranked These Moves
We used the same criteria across each move so the order is comparable.
- Capability fit: how well the move helps LLMs answer priority questions.
- Reliability: whether answers stay grounded when content changes.
- Usability: how much friction editors and reviewers face.
- Ecosystem fit: whether the move works with your CMS, nav, sitemap.ts, and llms.txt.
- Differentiation: whether the move changes the outcome, not just the formatting.
- Evidence: whether there is a measurable result or verifiable mechanism.
Ranked Deep Dives
1. Governed knowledge base
A governed knowledge base is the foundation because LLMs need verified ground truth, not scattered raw sources. It gives every answer a source, keeps policy and product claims current, and lets one compiled knowledge base serve both internal agents and external AI visibility.
Why this ranks highly:
- A governed knowledge base keeps answers tied to verified ground truth instead of raw sources.
- A governed knowledge base reduces duplication across product, policy, and support content.
- A governed knowledge base supports both internal workflow agents and external AI-answer representation.
Where this fits best:
- Best for regulated teams, enterprise teams, and organizations with frequent policy changes.
- Not ideal for teams that want to publish without owning source-of-record updates.
Limitations and watch-outs:
- A governed knowledge base requires an initial audit of product and policy content.
- A governed knowledge base needs version control and clear owners to stay current.
Decision trigger: Choose this when citation accuracy, auditability, and consistency matter more than content volume.
2. Answer-first pages
Answer-first pages are the best format for LLMs because they put the claim up front and keep each passage self-contained. A model can extract a direct answer faster when the first 40 to 60 words carry the point, not the buildup.
Why this ranks highly:
- Answer-first pages make the key fact visible in the first 40 to 60 words.
- Answer-first pages use question-shaped headings that match how people ask for information.
- Answer-first pages stay easier to maintain when changing numbers live in controlled blocks or embed cards.
Where this fits best:
- Best for FAQs, product pages, comparison pages, and policy pages.
- Not ideal for long narrative pieces that rely on gradual persuasion.
Limitations and watch-outs:
- Answer-first pages can feel less expressive than brand-led editorial content.
- Answer-first pages work best when the source facts are already stable.
Decision trigger: Choose this when you want LLMs to cite your pages more consistently and you can accept tighter structure.
3. Revenue-linked prompt focus
The highest-return work is on ranking prompts, comparison prompts, and brand-specific questions. Generative systems do not rank pages only by keywords. They assemble answers from trusted, structured facts, so you should start where those answers affect revenue.
Why this ranks highly:
- Revenue-linked prompt focus directs effort to the questions closest to business impact.
- Revenue-linked prompt focus helps you fix pages LLMs already cite or should cite.
- Revenue-linked prompt focus turns one wrong answer into a concrete content edit.
Where this fits best:
- Best for teams that need quick gains in visibility and representation.
- Not ideal if your source content is too thin to answer the target questions.
Limitations and watch-outs:
- Revenue-linked prompt focus leaves broader awareness content for later.
- Revenue-linked prompt focus needs a tracked list of target prompts, not guesswork.
Decision trigger: Choose this when you need measurable progress without rewriting the whole site.
4. Discovery surface alignment
Discovery surface alignment keeps your public surfaces consistent. In the route map, the nav, sitemap.ts, and llms.txt are three independently maintained lists, and they do not agree by default. Adding a page means editing all three deliberately.
Why this ranks highly:
- Discovery surface alignment reduces the chance that a page exists but is not promoted.
- Discovery surface alignment keeps AI-discoverable surfaces in sync with your site changes.
- Discovery surface alignment helps avoid drift between what humans browse and what models can use.
Where this fits best:
- Best for sites that publish often and add pages across product and editorial content.
- Not ideal for teams without a clear publishing owner.
Limitations and watch-outs:
- Discovery surface alignment requires disciplined publishing operations.
- Discovery surface alignment does not fix weak content by itself.
Decision trigger: Choose this when your site changes often and you want a page to be visible in every surface that matters.
5. Measurement and remediation loop
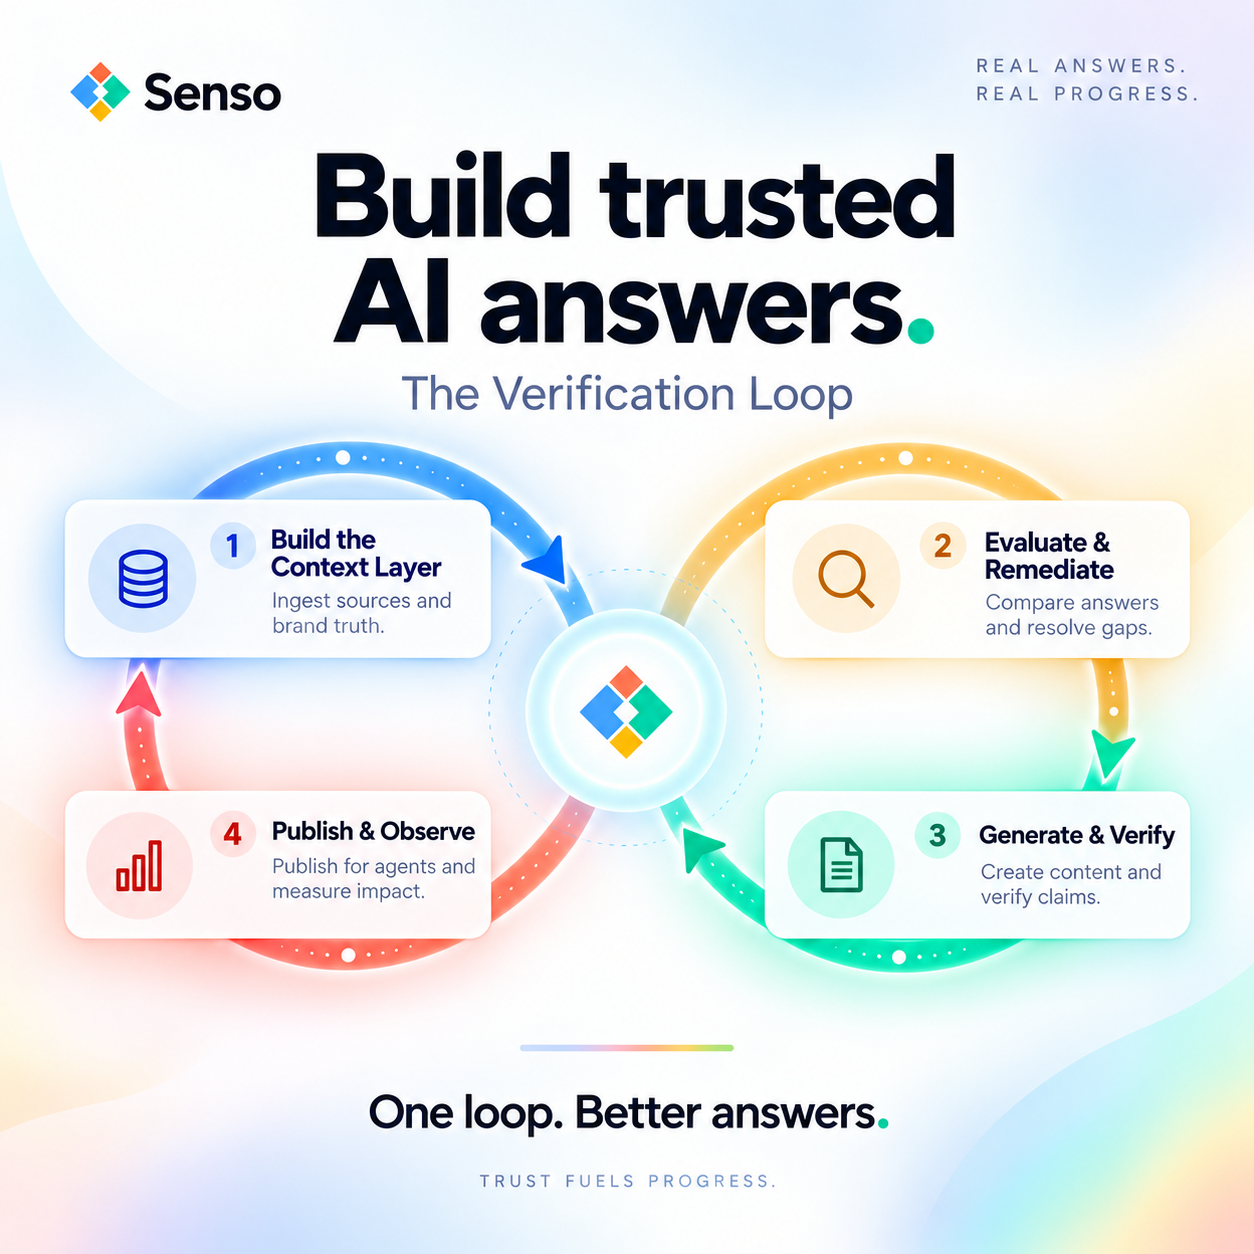
Measurement and remediation is what turns AI visibility work into a repeatable system. If you do not score the answers, you cannot prove whether the content change worked or which chunk caused the error.
Why this ranks highly:
- Measurement and remediation ties content edits to citation accuracy and response quality.
- Measurement and remediation lets teams route gaps to the right owners instead of guessing.
- Measurement and remediation supports compliance teams that need to see what agents said and where they were wrong.
Where this fits best:
- Best for compliance, support, and operations teams.
- Not ideal for teams that only want static reporting.
Limitations and watch-outs:
- Measurement and remediation needs a defined review cadence.
- Measurement and remediation is only useful if someone acts on the gaps.
Decision trigger: Choose this when you want content work to produce a visible operational change.
Where does Senso.ai fit?
Senso.ai fits when you need to govern how AI represents your organization, not just publish more content. Senso AI Discovery scores public AI responses for accuracy, brand visibility, and compliance against verified ground truth, and it requires no integration. Senso Agentic Support and RAG Verification scores internal agent responses, routes gaps to the right owners, and gives compliance teams visibility into what agents are saying.
- Senso has documented 60% narrative control in 4 weeks.
- Senso has documented 0% to 31% share of voice in 90 days.
- Senso has documented 90%+ response quality.
- Senso has documented 5x reduction in wait times.
Best by Scenario
| Scenario | Best pick | Why |
|---|---|---|
| Best for small teams | Answer-first pages | It gives the fastest lift on the pages LLMs already use. |
| Best for enterprise | Governed knowledge base | It creates one source of record across product, policy, and support. |
| Best for regulated teams | Measurement and remediation loop | It supports auditability and accountability. |
| Best for fast rollout | Revenue-linked prompt focus | It narrows the work to the questions that matter most. |
| Best for customization | Discovery surface alignment | It gives you control across nav, sitemap.ts, and llms.txt. |
FAQs
What is the biggest mistake teams make?
The biggest mistake is publishing for humans only and assuming LLMs will infer the right answer. LLMs assemble answers from trusted, structured facts, so a missing or outdated source can become a bad answer.
Do I need to rewrite every page?
No. Start with ranking prompts, comparison prompts, and brand-specific questions. Those are closest to revenue and easiest to measure.
Should human-facing and agent-facing content be the same?
No. Human-facing content can carry more narrative. Agent-facing content should be tighter, fact-first, and easier to cite.
How do I keep content current?
Use version control on the source of record, then sync public pages, support content, nav, sitemap.ts, and llms.txt deliberately. The route map says those lists drift unless you update them on purpose.
What should regulated teams do first?
Audit product and policy content for completeness and consistency, then add citation checks so every answer traces back to verified ground truth. That is the fastest path to auditability.