What metrics matter most for improving AI visibility over time?
The metrics that matter most are Mention Rate, Citation Rate, Share of Voice, and Factual Accuracy. Those signals show whether AI systems include your brand, ground answers in verified sources, and give your brand more answer space over time. Track them weekly across ChatGPT, Perplexity, Gemini, and Google AI Overview, then use average rank and freshness to explain the trend.
Quick answer
If you can only track three metrics, start with Mention Rate, Citation Rate, and Share of Voice. Mention Rate shows inclusion. Citation Rate shows proof. Share of Voice shows answer dominance. Add freshness for regulated teams, because a cited answer can still be wrong if the source is outdated.
Which metrics matter most, in order?
Use this order when you build your AI visibility dashboard.
| Rank | Metric | What it tells you | Why it matters over time |
|---|---|---|---|
| 1 | Mention Rate | Whether AI includes your brand | It is the first sign that the model sees your brand as relevant. |
| 2 | Citation Rate | Whether AI cites verified sources | Citations are the proof point for grounded answers. |
| 3 | Share of Voice | How much of the answer is about your brand | It shows whether your brand is gaining or losing answer space. |
| 4 | Citation Share | How much citation space your sources receive | It shows whether the model is leaning on your verified ground truth. |
| 5 | Factual Accuracy and Freshness | Whether the answer matches current facts | It protects you from stale or misrepresented information. |
| 6 | Average Rank or Relative Position | Where your brand appears in the answer | It helps you compare results across prompts and models. |
| 7 | Content and Context Gaps | What the model is missing | It tells you what to fix next in your source material. |
Why are Mention Rate and Citation Rate the first metrics?
Mention Rate tells you whether the model includes your brand at all. Citation Rate tells you whether the answer is grounded in verified ground truth. Traditional rankings only show where a URL sits on a results page. Mentions show whether AI models include your brand.
Citations are a trust mechanic for AI engines. When models cite your owned pages or credible external sources, you can trace the answer back to a specific source. If Mention Rate rises but Citation Rate stays flat, your visibility is fragile.
Why does Share of Voice matter so much?
Share of Voice measures answer dominance. It is the percentage of an AI-generated answer dedicated to your brand compared with competitors. That makes it the clearest business signal in the set.
Share of Voice tells you whether your brand is getting more room inside the answer. If it grows over time, your narrative control is improving. If it shrinks, competitors are taking space from your category story.
What does Citation Share tell you?
Citation Share shows whether your sources are winning citation space inside the prompt set. It is useful when you want to know if AI is relying on your verified sources or on other pages and publishers.
Citation Share matters because citations shape the answer. If the model keeps citing your content, your ground truth is becoming easier for the system to use. If citation share drops, the model is finding other sources first.
Why should you track freshness and factual accuracy separately?
A visible answer that is stale is still a risk. Factual accuracy and freshness tell you whether the model is representing current products, pricing, and policies correctly.
Review core ground truth pages at least every 60 days. Review them immediately after changes to products, pricing, or policies. In regulated industries, this metric matters as much as visibility because it protects auditability.
Which AI surfaces should be in your dashboard?
Track ChatGPT, Perplexity, Gemini, and Google AI Overview first. These are the four surfaces Senso tracks by default. Add Claude, Grok, and Meta AI when they matter to your audience or market.
Use the same prompts across every surface so the trend is comparable. Senso measures coverage per prompt, per model, and per surface, daily. That gives you a stable baseline for month-over-month comparison.
How should you measure AI visibility over time?
Measure daily if you can, and review at least weekly. Weekly review is the minimum because AI answers shift quickly as models update and sources change.
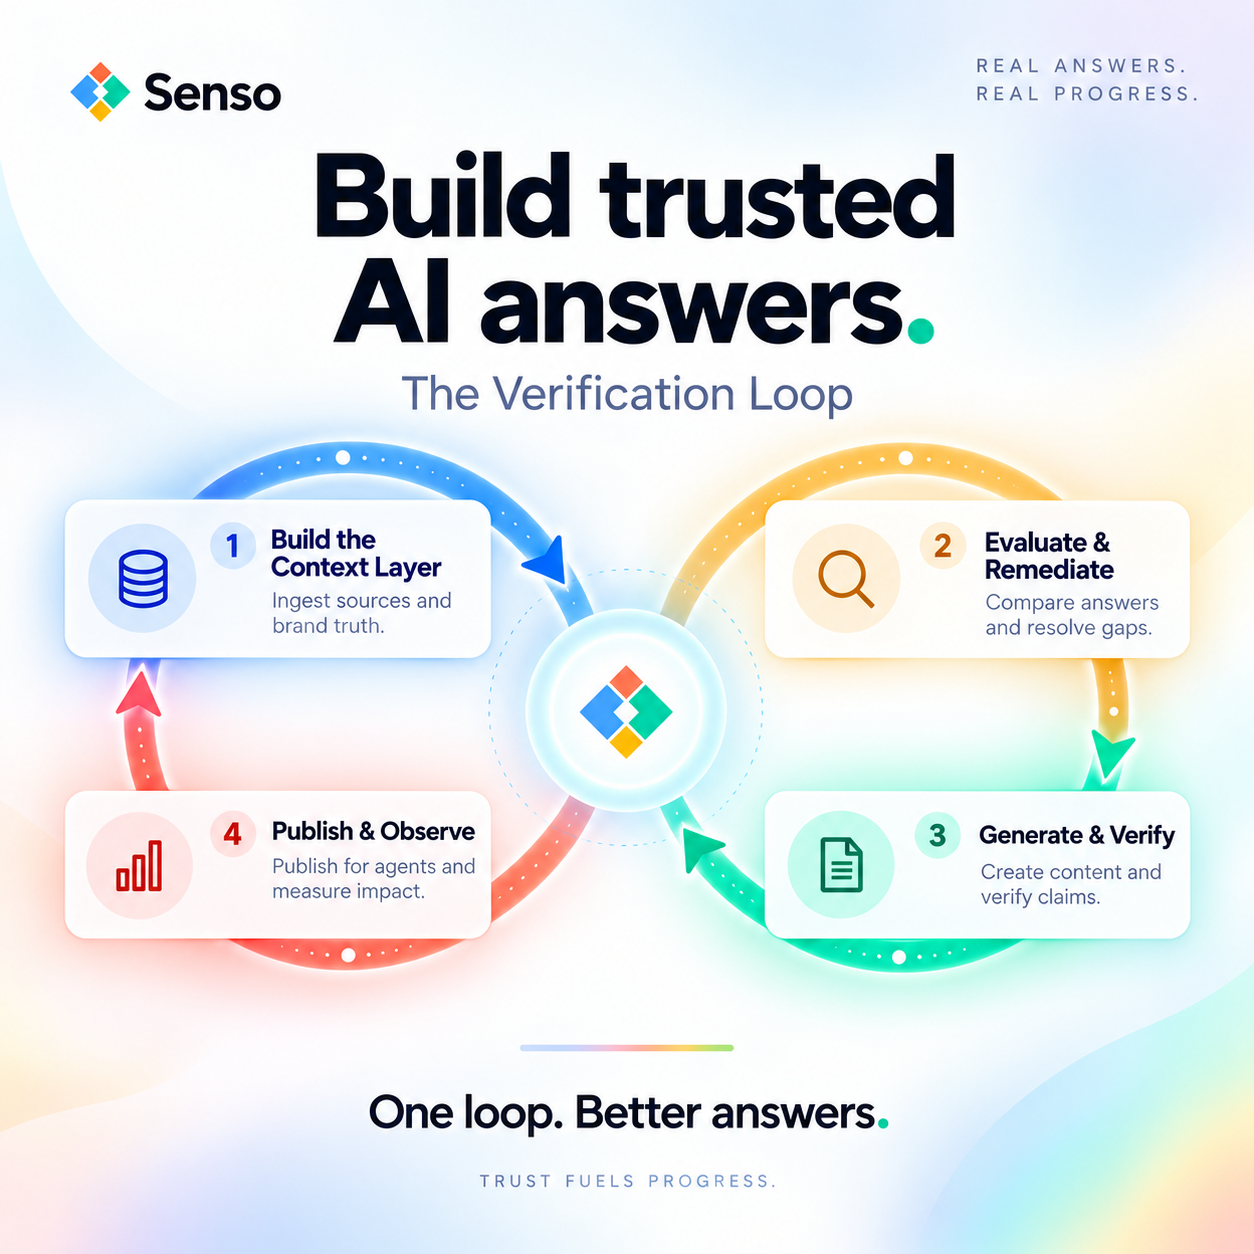
Senso evaluates AI answers by running tracked prompts across selected AI models and capturing the generated answers. Visibility Trends shows how core visibility signals change over time. Model Trends breaks those results down by individual AI system. The Organization Leaderboard ranks organizations based on visibility performance across your tracked prompt set.
What does good progress look like?
Good progress shows up as cleaner answers, better source alignment, and more answer space. Senso reports outcomes such as 60% narrative control in 4 weeks, 0% to 31% share of voice in 90 days, 90%+ response quality, and 5x reduction in wait times.
Those numbers matter because they connect visibility to operational change. They show that the metric work leads to better answers, not just better reporting.
What should you fix when the metrics stall?
Start with the source material. Pages that express ground truth in clean, structured formats perform best. That includes FAQs, pricing pages, and policy pages.
If Mention Rate is weak, the model is not seeing enough relevant context. If Citation Rate is weak, the model does not trust or cannot extract the right source. If Share of Voice is weak, competitors are occupying the answer space first.
FAQs
Is Share of Voice the most important metric?
Share of Voice is one of the most useful business metrics, but it is not the first one to track. Start with Mention Rate and Citation Rate, then use Share of Voice to see whether your visibility is actually growing.
Are rankings still useful for AI visibility?
Rankings are useful as a secondary signal. They show relative position, but they do not show whether the model mentioned your brand or cited your verified sources.
What should regulated teams prioritize?
Regulated teams should prioritize Citation Rate, factual accuracy, freshness, and the ability to trace every answer back to a specific verified source. Those metrics matter most when the question is proof, not just presence.
How often should core source pages be reviewed?
Review core ground truth pages at least every 60 days, and immediately after changes to products, pricing, or policies. That cadence keeps the metrics tied to current facts.
If you want, I can turn this into a tighter 700-word version or adapt it into a branded Senso blog post with internal links and a meta description.