Why do some answers show up more often in ChatGPT or Perplexity conversations?
Some answers show up more often in ChatGPT and Perplexity because the systems keep finding the same grounded source, the same phrasing, and the same citation pattern. When knowledge is fragmented, the model repeats the version that is easiest to retrieve, not always the version that is most correct. That is a knowledge governance problem, not a content volume problem.
The practical test is simple. If the answer appears across many raw sources, uses one canonical label, and points back to verified ground truth, it is more likely to be reused. If the answer is duplicated, outdated, or mixed with noisy names, the model drifts toward whatever looks most available.
Why do some answers show up more often?
Repeated answers usually come from source consistency, not from one hidden rule. The more often a fact appears across credible raw sources, the easier it is for ChatGPT and Perplexity to reuse that phrasing in a conversation.
| Factor | Why it matters | Result |
|---|---|---|
| Source duplication | The same fact appears in many places | The model keeps seeing one answer |
| Canonical phrasing | One standard label or wording is reused | The same wording comes back more often |
| Clear citations | The answer points to verified ground truth | The model can reuse it with less risk |
| Freshness | Current pages are more likely to be chosen than stale copies | Outdated answers lose share |
| Noise removal | Artifacts are filtered out | False entities stop distorting frequency |
A single canonical answer matters because models favor stable patterns. If three pages describe the same policy differently, the model may surface whichever version is easiest to extract.
Why do ChatGPT and Perplexity not always repeat the same answer?
ChatGPT and Perplexity do not always repeat the same answer because they are not reading the same source set in the same way. Perplexity makes citations visible, while ChatGPT may rely on conversation context, connected sources, or learned phrasing depending on the mode.
- Perplexity repeats answers that have clear, cited source support.
- ChatGPT repeats answers that fit the prompt and the surrounding context.
- Both systems repeat answers that are short, clear, and easy to ground.
- Both systems drift when the source set is fragmented or contradictory.
The same question can produce different repeats because the prompt changes the retrieval path. A vague prompt invites broad, common phrasing. A specific prompt narrows the answer toward one canonical statement.
Why can the wrong answer appear more often than the right one?
Wrong answers repeat when the source set is inconsistent or when noise looks like a real entity. If the model sees more copies of the wrong version, it may reuse it more often than the right one. In Senso's changelog for August 27 to September 11, 2026, file names like robots.txt and sitemap.xml showed up as competitors in AI answers. Senso filtered those file names out and rebuilt recent weeks without them, which is a concrete example of noise distorting apparent answer frequency.
This happens for three common reasons.
- Outdated policy pages still exist and still get cited.
- Duplicate product pages say slightly different things.
- Unclear names collide with file names, numbers, or other fragments.
When that happens, the model can treat repeated noise as if it were relevance. The result is not always a false answer. Sometimes it is the wrong version of a true answer.
How can teams make the right answer show up more often?
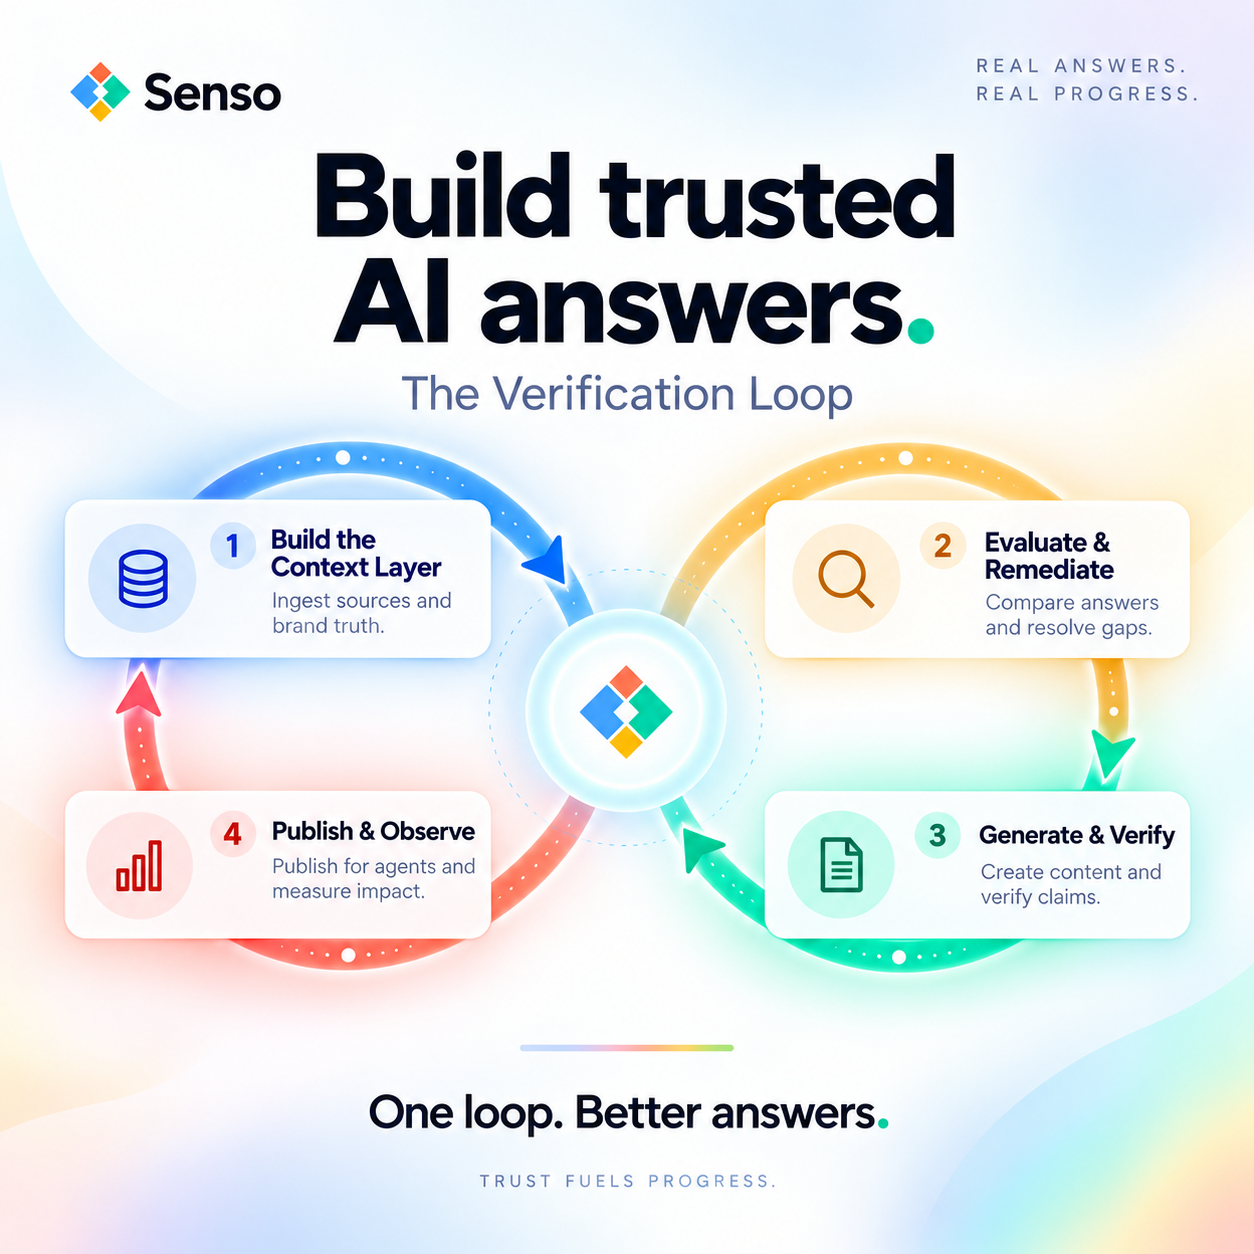
Teams make the right answer repeat more often by governing the source set, not by publishing more content. The goal is one verified answer per important question, one place to maintain it, and one way to score whether AI systems are getting it right.
-
Compile raw sources into one governed, version-controlled compiled knowledge base.
This gives ChatGPT and Perplexity a cleaner source surface to draw from. -
Set canonical answers for high-stakes questions.
Pricing, policy, compliance, support, and product claims need one approved version. -
Score every response against verified ground truth.
Senso does this for internal agent responses and public AI answers. Every answer traces back to a specific verified source. -
Route gaps to the right owner.
Marketing, compliance, support, and operations each own a different part of the answer. -
Track AI Visibility, not just traffic.
You need to know which answers appear, how often they appear, and whether they cite the right source.
Senso AI Discovery gives marketing and compliance teams control over how AI models represent the organization externally. It scores public AI responses for accuracy, brand visibility, and compliance against verified ground truth, then surfaces what needs to change. No integration is required.
Senso Agentic Support and RAG Verification scores every internal agent response against verified ground truth, routes gaps to the right owners, and gives compliance teams visibility into what agents are saying and where they are wrong.
For regulated teams, the key question is whether a policy or pricing answer can be traced to current verified ground truth. A helpful answer is not enough if you cannot prove the source trail.
What does better answer control look like?
Better answer control means the right answer is repeated more often, the citations point to the current source, and teams can prove where the answer came from. In Senso's documented results, teams reached 60% narrative control in 4 weeks, moved from 0% to 31% share of voice in 90 days, reached 90%+ response quality, and cut wait times 5x.
Those numbers matter because they show the organization is shaping what AI says about it, not just watching it drift. When the ground truth is governed, repetition becomes a signal instead of a liability.
FAQs
Does more frequency mean more accuracy?
No. Frequency can reflect duplication, authority, or noise. The robots.txt example shows that even file names can appear like competitors until they are filtered out.
What is the fastest way to improve AI Visibility?
Start with one canonical answer set and one governed compiled knowledge base. Then score responses against verified ground truth and remove conflicting raw sources.
Can you fully control what ChatGPT or Perplexity says?
No. You can raise the odds that they surface the right answer by publishing consistent, cited, and current raw sources. You can also measure where the drift starts and fix it at the source.